Current-centric measurements
The current frame becomes a transient anchor. Predict window-relative poses and a local pointmap, rather than carrying a first-frame or historical coordinate system through the stream.
Formulation · §3.1Streaming 3D Reconstruction with Transient Anchors
Accepted at CoRL 2026
Long-horizon online visual mapping requires continuous camera-motion and scene-geometry estimation under bounded computation. Recent feed-forward 3D reconstruction models provide strong geometric priors, but streaming variants often predict poses in a fixed or historically maintained coordinate system, leading to train–test mismatch, early-anchor attention bias, and accumulated drift. We propose Anchor3R, a current-centric streaming 3D reconstruction framework that predicts window-relative poses and local geometry in the current-frame coordinate system. Overlapping predictions form a dense relative-pose graph, supporting online pose updates and loop-aware motion averaging for global reconstruction. Experiments on indoor, outdoor, driving, and RGB-D benchmarks demonstrate improved long-horizon pose accuracy and dense reconstruction quality over existing streaming baselines. Despite being trained only on 48-frame sequences, Anchor3R directly generalizes to streams exceeding 10,000 frames while maintaining bounded GPU memory during online inference.
The current frame becomes a transient anchor. Predict window-relative poses and a local pointmap, rather than carrying a first-frame or historical coordinate system through the stream.
Formulation · §3.1An image-only cached pose-query Transformer reuses visual key/value states and rebuilds pose queries for each anchor. Stale coordinate hypotheses do not enter the next window; online GPU memory stays bounded.
Architecture · §3.2Overlapping predictions form redundant relative-pose constraints. Use them for online pose updates, then add loop-keyframe measurements and motion averaging to redistribute drift globally.
Pose recovery · §3.4
Image evidence persists; pose reasoning is transient. Decoupled frame attention computes reusable image states. Current-centric window attention combines cached patch keys/values with freshly instantiated reference/source pose-query groups. Only image-side states are cached; pose queries are discarded after each window. The heads decode window-relative poses and the current-frame pointmap with confidence.
DINOv2 extracts patch tokens. A 10-frame active window provides cached image evidence without an ever-growing GPU state.
Fresh reference/source query groups jointly decode window-relative poses. The point head predicts local geometry; training shares one scale factor between pose translations and pointmaps.
Overlapping windows add relative-pose edges. Recovered global poses place local pointmaps into a shared reconstruction.
Aggregate relative measurements from previously recovered frames with robust rotation and position medians. No loop detection or loop-keyframe reinsertion.
Reinsert retrieved loop keyframes to predict long-range edges. Joint rotation averaging with IRLS and robust L1 translation averaging with ADMM refine the graph.
004,541 frames1 / 4
campus_train012,042 frames1 / 4
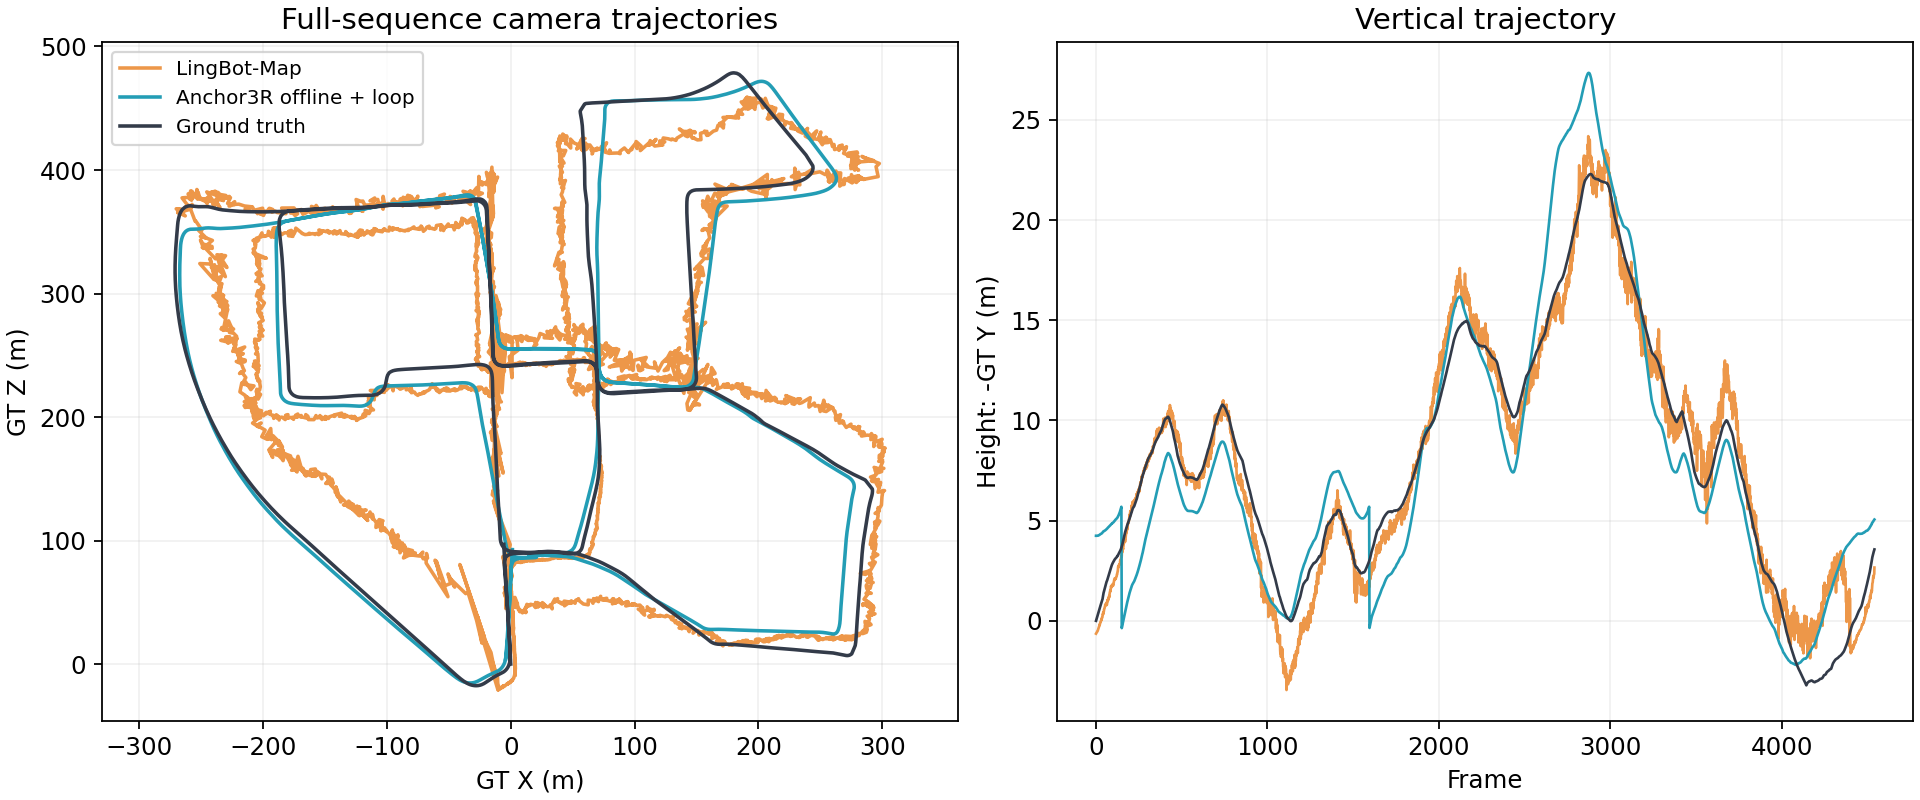
Both methods use one full-sequence Sim(3) alignment to GT. The default 20 m cutoff uses each point’s source-frame camera, not the viewing camera. Point clouds are sampled previews; these are not paper benchmark claims.
@article{tao2026anchor3r,
  title   = {Anchor3R: Streaming 3D Reconstruction with Transient Anchors for Long-Horizon Visual Mapping},
  author  = {Peilin Tao and Chong Cheng and Yuansen Du and Caiwei Song and Zhengqing Chen and Xiaoyang Guo and Wei Yin and Weiqiang Ren and Qian Zhang and Hainan Cui and Shuhan Shen},
  journal = {arXiv preprint arXiv:2606.05035},
  year    = {2026}
}